Benchmarks
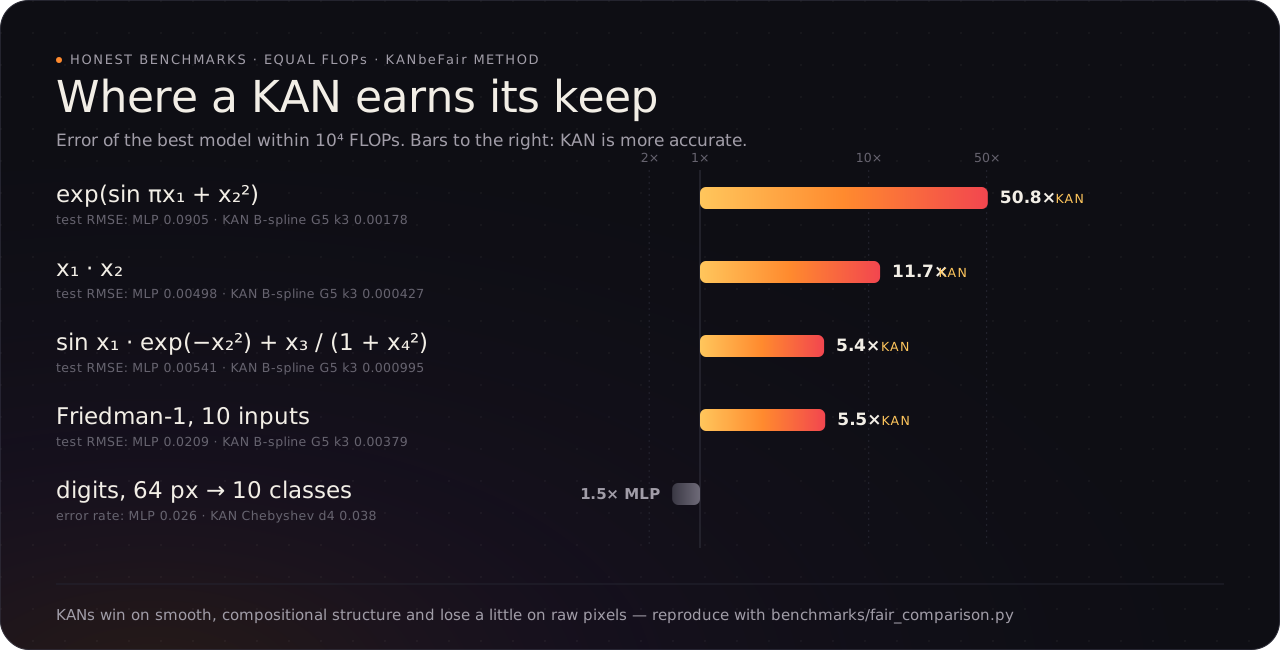
KAN vs MLP at equal FLOPs
benchmarks/fair_comparison.py, following KANbeFair: same optimiser, steps
and data, FLOPs counted by kanforge.flops; CPU, float32, seed 0, 18.10.2026.
Summary (best of each family within 10⁵ FLOPs per sample):
| task | best KAN | best MLP | |
|---|---|---|---|
| exp(sin(πx₁) + x₂²) | RMSE 1.5e-3 (B-spline) | 9.0e-2 | KAN ~60x more accurate |
| x₁ · x₂ | 4.3e-4 (B-spline) | 5.0e-3 | ~12x |
| sin(x₁)e^(−x₂²) + x₃/(1 + x₄²) | 9.9e-4 (B-spline) | 5.4e-3 | ~5x |
| Friedman-1 (smooth tabular) | 3.8e-3 (B-spline) | 2.1e-2 | ~5x |
| digits (classification) | accuracy 0.974 | 0.978 | MLP slightly better, clearly better at small budgets |
KANs win on smooth, low-dimensional functions — symbolic formulas and physics — and are not better on high-dimensional classification, the same picture as KANbeFair. One optimiser setting (Adam 3e-3, 3000 steps) for all models: a tuned MLP narrows the regression gaps; the comparison is about equal effort, not best possible results.
Full tables:
Adam lr 3e-3, 3000 steps, seed 0; metric: test RMSE (lower is better) or accuracy (higher).
exp(sin(pi x1) + x2^2)
| model | width | params | FLOPs | RMSE |
|---|---|---|---|---|
| MLP | 4 | 17 | 57 | 0.7365 |
| MLP | 8 | 33 | 113 | 0.8418 |
| MLP | 16 | 65 | 225 | 0.1653 |
| MLP | 32 | 129 | 449 | 0.1221 |
| MLP | 64 | 257 | 897 | 0.09461 |
| MLP | 128 | 513 | 1793 | 0.09223 |
| MLP | 256 | 1025 | 3585 | 0.09047 |
| KAN B-spline G5 k3 | 1 | 29 | 824 | 0.04104 |
| KAN B-spline G5 k3 | 2 | 57 | 1135 | 0.01068 |
| KAN B-spline G5 k3 | 4 | 113 | 1757 | 0.003746 |
| KAN B-spline G5 k3 | 8 | 225 | 3001 | 0.00178 |
| KAN B-spline G5 k3 | 16 | 449 | 5489 | 0.001933 |
| KAN B-spline G5 k3 | 32 | 897 | 10465 | 0.001498 |
| KAN Chebyshev d4 | 1 | 20 | 101 | 0.06972 |
| KAN Chebyshev d4 | 2 | 39 | 159 | 0.1051 |
| KAN Chebyshev d4 | 4 | 77 | 275 | 0.02533 |
| KAN Chebyshev d4 | 8 | 153 | 507 | 0.01795 |
| KAN Chebyshev d4 | 16 | 305 | 971 | 0.01237 |
| KAN Chebyshev d4 | 32 | 609 | 1899 | 0.008207 |
Best within a FLOP budget:
| FLOPs <= | KAN B-spline G5 k3 | KAN Chebyshev d4 | MLP |
|---|---|---|---|
| 1e+02 | — | — | 0.7365 |
| 1e+03 | 0.04104 | 0.01237 | 0.09461 |
| 1e+04 | 0.00178 | 0.008207 | 0.09047 |
| 1e+05 | 0.001498 | 0.008207 | 0.09047 |
x1 * x2
| model | width | params | FLOPs | RMSE |
|---|---|---|---|---|
| MLP | 4 | 17 | 57 | 0.02179 |
| MLP | 8 | 33 | 113 | 0.01013 |
| MLP | 16 | 65 | 225 | 0.007712 |
| MLP | 32 | 129 | 449 | 0.00605 |
| MLP | 64 | 257 | 897 | 0.006227 |
| MLP | 128 | 513 | 1793 | 0.004981 |
| MLP | 256 | 1025 | 3585 | 0.01809 |
| KAN B-spline G5 k3 | 1 | 29 | 824 | 0.1234 |
| KAN B-spline G5 k3 | 2 | 57 | 1135 | 0.00069 |
| KAN B-spline G5 k3 | 4 | 113 | 1757 | 0.001973 |
| KAN B-spline G5 k3 | 8 | 225 | 3001 | 0.0005986 |
| KAN B-spline G5 k3 | 16 | 449 | 5489 | 0.0004267 |
| KAN B-spline G5 k3 | 32 | 897 | 10465 | 0.0008165 |
| KAN Chebyshev d4 | 1 | 20 | 101 | 0.1516 |
| KAN Chebyshev d4 | 2 | 39 | 159 | 0.008885 |
| KAN Chebyshev d4 | 4 | 77 | 275 | 0.004261 |
| KAN Chebyshev d4 | 8 | 153 | 507 | 0.002174 |
| KAN Chebyshev d4 | 16 | 305 | 971 | 0.001584 |
| KAN Chebyshev d4 | 32 | 609 | 1899 | 0.001747 |
Best within a FLOP budget:
| FLOPs <= | KAN B-spline G5 k3 | KAN Chebyshev d4 | MLP |
|---|---|---|---|
| 1e+02 | — | — | 0.02179 |
| 1e+03 | 0.1234 | 0.001584 | 0.00605 |
| 1e+04 | 0.0004267 | 0.001584 | 0.004981 |
| 1e+05 | 0.0004267 | 0.001584 | 0.004981 |
sin(x1) exp(-x2^2) + x3 / (1 + x4^2)
| model | width | params | FLOPs | RMSE |
|---|---|---|---|---|
| MLP | 4 | 25 | 73 | 0.1081 |
| MLP | 8 | 49 | 145 | 0.06752 |
| MLP | 16 | 97 | 289 | 0.01212 |
| MLP | 32 | 193 | 577 | 0.007397 |
| MLP | 64 | 385 | 1153 | 0.006718 |
| MLP | 128 | 769 | 2305 | 0.00694 |
| MLP | 256 | 1537 | 4609 | 0.005414 |
| KAN B-spline G5 k3 | 1 | 47 | 1372 | 0.1419 |
| KAN B-spline G5 k3 | 2 | 93 | 1719 | 0.0789 |
| KAN B-spline G5 k3 | 4 | 185 | 2413 | 0.001661 |
| KAN B-spline G5 k3 | 8 | 369 | 3801 | 0.0009948 |
| KAN B-spline G5 k3 | 16 | 737 | 6577 | 0.001119 |
| KAN B-spline G5 k3 | 32 | 1473 | 12129 | 0.001408 |
| KAN Chebyshev d4 | 1 | 32 | 167 | 0.1416 |
| KAN Chebyshev d4 | 2 | 63 | 249 | 0.09131 |
| KAN Chebyshev d4 | 4 | 125 | 413 | 0.007006 |
| KAN Chebyshev d4 | 8 | 249 | 741 | 0.007707 |
| KAN Chebyshev d4 | 16 | 497 | 1397 | 0.006881 |
| KAN Chebyshev d4 | 32 | 993 | 2709 | 0.00445 |
Best within a FLOP budget:
| FLOPs <= | KAN B-spline G5 k3 | KAN Chebyshev d4 | MLP |
|---|---|---|---|
| 1e+02 | — | — | 0.1081 |
| 1e+03 | — | 0.007006 | 0.007397 |
| 1e+04 | 0.0009948 | 0.00445 | 0.005414 |
| 1e+05 | 0.0009948 | 0.00445 | 0.005414 |
Friedman-1 (10 inputs)
| model | width | params | FLOPs | RMSE |
|---|---|---|---|---|
| MLP | 4 | 49 | 121 | 0.1092 |
| MLP | 8 | 97 | 241 | 0.07352 |
| MLP | 16 | 193 | 481 | 0.02965 |
| MLP | 32 | 385 | 961 | 0.03041 |
| MLP | 64 | 769 | 1921 | 0.02607 |
| MLP | 128 | 1537 | 3841 | 0.02244 |
| MLP | 256 | 3073 | 7681 | 0.0209 |
| KAN B-spline G5 k3 | 1 | 101 | 3016 | 0.2539 |
| KAN B-spline G5 k3 | 2 | 201 | 3471 | 0.1581 |
| KAN B-spline G5 k3 | 4 | 401 | 4381 | 0.01306 |
| KAN B-spline G5 k3 | 8 | 801 | 6201 | 0.003787 |
| KAN B-spline G5 k3 | 16 | 1601 | 9841 | 0.006346 |
| KAN B-spline G5 k3 | 32 | 3201 | 17121 | 0.007644 |
| KAN Chebyshev d4 | 1 | 68 | 365 | 0.2523 |
| KAN Chebyshev d4 | 2 | 135 | 519 | 0.2114 |
| KAN Chebyshev d4 | 4 | 269 | 827 | 0.02568 |
| KAN Chebyshev d4 | 8 | 537 | 1443 | 0.02147 |
| KAN Chebyshev d4 | 16 | 1073 | 2675 | 0.01336 |
| KAN Chebyshev d4 | 32 | 2145 | 5139 | 0.02354 |
Best within a FLOP budget:
| FLOPs <= | KAN B-spline G5 k3 | KAN Chebyshev d4 | MLP |
|---|---|---|---|
| 1e+03 | — | 0.02568 | 0.02965 |
| 1e+04 | 0.003787 | 0.01336 | 0.0209 |
| 1e+05 | 0.003787 | 0.01336 | 0.0209 |
digits (64 inputs, 10 classes)
| model | width | params | FLOPs | accuracy |
|---|---|---|---|---|
| MLP | 4 | 310 | 634 | 0.908 |
| MLP | 8 | 610 | 1258 | 0.962 |
| MLP | 16 | 1210 | 2506 | 0.96 |
| MLP | 32 | 2410 | 5002 | 0.974 |
| MLP | 64 | 4810 | 9994 | 0.974 |
| MLP | 128 | 9610 | 19978 | 0.974 |
| MLP | 256 | 19210 | 39946 | 0.978 |
| KAN B-spline G5 k3 | 1 | 677 | 17983 | 0.432 |
| KAN B-spline G5 k3 | 2 | 1344 | 19572 | 0.758 |
| KAN B-spline G5 k3 | 4 | 2678 | 22750 | 0.898 |
| KAN B-spline G5 k3 | 8 | 5346 | 29106 | 0.968 |
| KAN B-spline G5 k3 | 16 | 10682 | 41818 | 0.972 |
| KAN B-spline G5 k3 | 32 | 21354 | 67242 | 0.974 |
| KAN Chebyshev d4 | 1 | 455 | 2264 | 0.504 |
| KAN Chebyshev d4 | 2 | 900 | 3174 | 0.744 |
| KAN Chebyshev d4 | 4 | 1790 | 4994 | 0.852 |
| KAN Chebyshev d4 | 8 | 3570 | 8634 | 0.962 |
| KAN Chebyshev d4 | 16 | 7130 | 15914 | 0.962 |
| KAN Chebyshev d4 | 32 | 14250 | 30474 | 0.972 |
Best within a FLOP budget:
| FLOPs <= | KAN B-spline G5 k3 | KAN Chebyshev d4 | MLP |
|---|---|---|---|
| 1e+03 | — | — | 0.908 |
| 1e+04 | — | 0.962 | 0.974 |
| 1e+05 | 0.974 | 0.972 | 0.978 |
Speed of the fused kernels
Benchmarks
benchmarks/bench_kernels.py — one KANLinear layer, median of 20 runs after
warm-up, float32. "fwd+bwd" is forward plus backward into all parameters (and
into the input for PyTorch). Plain ops = basis tensor + matrix product;
kernel = fused kernel of kanforge.kernels.
Machine: Apple M5, 16 GB, PyTorch 2.14 (MPS), MLX 0.32 — 18.10.2026. Timings on this machine vary by ~±15 % between runs.
PyTorch MPS
| basis | batch x in x out | fwd ops | fwd kernel | fwd+bwd ops | fwd+bwd kernel |
|---|---|---|---|---|---|
| bspline G8 k3 | 1024x64x64 | 3.57 ms | 0.90 ms | 6.69 ms | 2.04 ms |
| bspline G8 k3 | 8192x128x128 | 109.44 ms | 19.43 ms | 204.61 ms | 69.31 ms |
| bspline G8 k3 | 32768x64x64 | 185.66 ms | 18.71 ms | 361.65 ms | 44.76 ms |
| chebyshev d8 | 1024x64x64 | 0.73 ms | 0.88 ms | 1.36 ms | 1.77 ms |
| chebyshev d8 | 8192x128x128 | 11.89 ms | 13.65 ms | 26.50 ms | 29.96 ms |
| chebyshev d8 | 32768x64x64 | 26.20 ms | 14.00 ms | 56.71 ms | 25.93 ms |
| rbf 8 | 1024x64x64 | 1.18 ms | 0.48 ms | 1.99 ms | 0.92 ms |
| rbf 8 | 8192x128x128 | 17.87 ms | 6.12 ms | 38.37 ms | 17.71 ms |
| rbf 8 | 32768x64x64 | 32.54 ms | 7.98 ms | 71.94 ms | 17.59 ms |
| fourier 4 | 1024x64x64 | 0.85 ms | 0.78 ms | 1.32 ms | 1.52 ms |
| fourier 4 | 8192x128x128 | 10.23 ms | 6.58 ms | 22.69 ms | 19.09 ms |
| fourier 4 | 32768x64x64 | 20.34 ms | 7.96 ms | 41.50 ms | 18.09 ms |
MLX (Metal)
| basis | batch x in x out | fwd ops | fwd kernel | fwd+bwd ops | fwd+bwd kernel |
|---|---|---|---|---|---|
| bspline G8 k3 | 1024x64x64 | 1.80 ms | 0.62 ms | 1.25 ms | 1.16 ms |
| bspline G8 k3 | 8192x128x128 | 30.31 ms | 17.49 ms | 35.14 ms | 29.86 ms |
| bspline G8 k3 | 32768x64x64 | 64.72 ms | 18.08 ms | 69.33 ms | 28.09 ms |
| chebyshev d8 | 1024x64x64 | 0.57 ms | 0.78 ms | 0.64 ms | 1.04 ms |
| chebyshev d8 | 8192x128x128 | 11.12 ms | 12.66 ms | 11.77 ms | 20.27 ms |
| chebyshev d8 | 32768x64x64 | 23.74 ms | 13.67 ms | 24.83 ms | 17.15 ms |
| rbf 8 | 1024x64x64 | 0.56 ms | 0.45 ms | 0.65 ms | 0.51 ms |
| rbf 8 | 8192x128x128 | 6.48 ms | 7.87 ms | 8.81 ms | 12.96 ms |
| rbf 8 | 32768x64x64 | 15.62 ms | 7.25 ms | 19.13 ms | 10.91 ms |
| fourier 4 | 1024x64x64 | 0.51 ms | 0.60 ms | 0.63 ms | 0.91 ms |
| fourier 4 | 8192x128x128 | 4.67 ms | 5.62 ms | 7.83 ms | 12.53 ms |
| fourier 4 | 32768x64x64 | 9.61 ms | 9.08 ms | 11.46 ms | 12.59 ms |
PyTorch CUDA (Triton)
RTX 3060 12 GB, driver 535, PyTorch 2.6.0+cu124, Triton 3.2.0, idle GPU — 18.10.2026.
tl.dot runs with IEEE float32 (no TF32), like the plain-ops reference.
| basis | batch x in x out | fwd ops | fwd kernel | fwd+bwd ops | fwd+bwd kernel |
|---|---|---|---|---|---|
| bspline G8 k3 | 1024x64x64 | 0.74 ms | 0.50 ms | 1.72 ms | 0.94 ms |
| bspline G8 k3 | 8192x128x128 | 8.46 ms | 8.22 ms | 21.59 ms | 17.39 ms |
| bspline G8 k3 | 32768x64x64 | 16.46 ms | 8.24 ms | 41.50 ms | 18.87 ms |
| chebyshev d8 | 1024x64x64 | 0.26 ms | 0.33 ms | 0.91 ms | 0.86 ms |
| chebyshev d8 | 8192x128x128 | 2.63 ms | 4.33 ms | 6.46 ms | 8.78 ms |
| chebyshev d8 | 32768x64x64 | 5.02 ms | 4.44 ms | 11.89 ms | 9.62 ms |
| rbf 8 | 1024x64x64 | 0.24 ms | 0.27 ms | 0.72 ms | 0.63 ms |
| rbf 8 | 8192x128x128 | 2.64 ms | 3.91 ms | 7.07 ms | 8.38 ms |
| rbf 8 | 32768x64x64 | 4.96 ms | 4.01 ms | 12.89 ms | 9.23 ms |
| fourier 4 | 1024x64x64 | 0.17 ms | 0.40 ms | 0.59 ms | 0.98 ms |
| fourier 4 | 8192x128x128 | 1.41 ms | 4.40 ms | 3.76 ms | 10.64 ms |
| fourier 4 | 32768x64x64 | 2.53 ms | 4.46 ms | 6.30 ms | 11.57 ms |
JAX (Pallas)
RTX 3060, JAX 0.6.2 (CUDA 12), idle GPU, 18.10.2026 — benchmarks/bench_jax.py,
both paths jit-compiled with IEEE float32 products. fwd+bwd = gradient with
respect to coefficients and input.
| basis | batch x in x out | fwd ops | fwd kernel | fwd+bwd ops | fwd+bwd kernel |
|---|---|---|---|---|---|
| bspline G8 k3 | 1024x64x64 | 0.15 ms | 0.43 ms | 0.39 ms | 1.00 ms |
| bspline G8 k3 | 8192x128x128 | 1.20 ms | 8.02 ms | 4.78 ms | 20.68 ms |
| bspline G8 k3 | 32768x64x64 | 1.90 ms | 7.52 ms | 8.30 ms | 21.74 ms |
| chebyshev d8 | 1024x64x64 | 0.10 ms | 0.15 ms | 0.17 ms | 0.45 ms |
| chebyshev d8 | 8192x128x128 | 0.60 ms | 1.88 ms | 1.72 ms | 10.82 ms |
| chebyshev d8 | 32768x64x64 | 0.95 ms | 1.85 ms | 2.16 ms | 10.99 ms |
| rbf 8 | 1024x64x64 | 0.09 ms | 0.17 ms | 0.23 ms | 0.49 ms |
| rbf 8 | 8192x128x128 | 0.51 ms | 2.53 ms | 1.49 ms | 12.24 ms |
| rbf 8 | 32768x64x64 | 0.75 ms | 2.44 ms | 1.74 ms | 12.15 ms |
| fourier 4 | 1024x64x64 | 0.09 ms | 0.39 ms | 0.17 ms | 0.89 ms |
| fourier 4 | 8192x128x128 | 0.51 ms | 7.65 ms | 1.73 ms | 19.30 ms |
| fourier 4 | 32768x64x64 | 0.72 ms | 7.21 ms | 2.40 ms | 20.20 ms |
XLA fuses the plain path very well (B-splines: 1.9 ms here vs 16 ms for plain
PyTorch on the same GPU); the first Pallas kernels (a loop over inputs with
scalar knot loads) are 2–10x slower, so auto never uses them in JAX.
What backend="auto" does with this
kanforge.kernels.plan.AUTO_KINDS: the kernel only where it won both columns.
- PyTorch MPS: B-splines (3–9x on fwd+bwd) and bumps — RBF, Mexican hat, DoG, RSWAF (2–4x).
- MLX: B-splines (1.1–2.5x). RBF is mixed, Chebyshev and Fourier are slower: MLX's own fused graph is already fast for them.
- Chebyshev-family polynomials and Fourier: plain ops by default; on MPS the
kernel is about even for small batches and 2x faster for 32k rows, choose
it with
backend="kernel". - JAX: never (plain XLA is faster, see above);
backend="kernel"still runs Pallas. - CUDA (Triton): B-splines (1.2–2.2x on fwd+bwd). Chebyshev and RBF win only for large batches, Fourier is 2–3x slower than cuBLAS + fused cos/sin. Correctness: the full suite passes on the RTX 3060 (and in CI under the Triton interpreter). ROCm is untested.